
Margin of Safety #68: What If Your Security Backlog Were Public?
Jimmy Park, Kathryn Shih
September 29, 2026
- Blog Post
Learnings from OpenAI’s latest security snafu
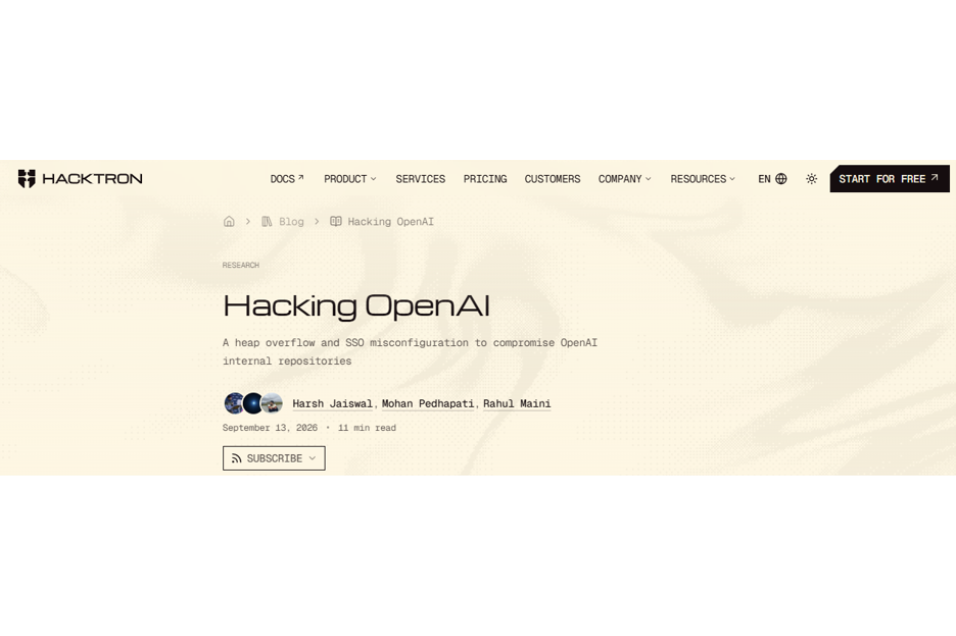
Another week, another cybersecurity debacle with a frontier lab. This time it came out that Hacktron, a next-gen, AI enabled pentester, was able chain 2 issues and gain access to OpenAI’s source repo:
- An unpatched image processing vulnerability in the open source forum software
- An SSO misconfiguration allowing escalation from forum-level compromise to other systems using the same SSO
Source: Hacktron blog post
We recognize the confirmation bias in our earlier predictions – that security teams need to increasingly get all of the basics correct. Agents are driving the cost of information discovery towards zero. That means that information is free as in beer, and (as other people have written), security by obscurity dies. A practical and perhaps scary way to decide if you’re ready for that world: imagine you had to post your security backlog for the world to see on company.com/backlog. How much leverage would this give different categories of attackers?[1] The more the answer is a lot of leverage for most attackers, the more concerned you should be.
At initial glance, it may seem like no companies could withstand that. We don’t agree: for at least some companies, their threat model has long included employee-compromise (we suspect most people who are concerned with state actors fall into this category). In such a world, you have to assume that a sufficiently sophisticated threat actor will be able to access any information a compromised member of the security team can access; this probably includes large portions of backlog (after all, employees have to know what they’re working on). But it’s also certainly the case that many companies have never had to worry about that level of threat or attack, and as a result are not prepared for it.
So what happens to those companies? Well, they get to choose between doing this work on their own schedule or as post-incident cleanup. So, we think it’d probably be better if CISOs pick a date they want to be ready by, and then work backwards. And the hardest part is likely not the technical work, but that the CISO (and their org) cannot do this alone. A very large share of the work falls on other teams, especially engineering. Getting cross-functional buy-in is a prerequisite for getting the work staffed & funded. We think the time (and macro marketing environment) is ripe for that buy-in, and it’s a question of rallying organizations behind a short list of tractable outcomes. In our mind, that means:
- Question the idea of security bug prioritization. Many prioritization schemes rely on the idea that some bugs are lower risk for exploit. But as discovery becomes cheaper and as we consistently see agents chain multiple issues, we think risk will even out. We think wise teams are moving to models where they use a combination of (A) a policy that when engineering touches a system, there must be no security regression, even if the risk might seem low in isolation (B) Systems that get touched must have some level of cleanup as part of that touching (eg, if you change something, clean up everything within some radius while you’re at it) (C) a hard target to burndown backlogs to zero(!) within the next [X] months, before you believe that your industry segment in particular is likely to face aggressively agentic attackers.
- Press on third party vendors. This is another category where security by obscurity has classically flourished: vendors, especially into the long tail and/or hardware adjacent, can have deeply variable posture of their own.
- Potentially most controversially: consider fully automated remediation. Historically, most tooling has stopped short of full remediation, since change is risky and can (for example) trigger outages, lock out employees, or otherwise adversely affect the IT environment. But implicit in the idea that you need to be careful with change is the tradeoff: the risk of a more weekly tested change has historically outweighed the security benefit of the rapid patch. However, the more you think that issues can (and will) be rapidly exploited, the more the balance should shift: under the assumption that everything-is-exploited, rushing fixes starts to seem like the safer choice. We don’t think this is limited to vulnerabilities. For example, if an alert suggests your VP of marketing is being spearfished on a Saturday, the balance might be shifting towards cutting credentials first and reaching the employee second; it all depends on how fast you assume adversaries are able to move. And at least from the discussions we’ve had with CISOs recently, they seem more and more open to this idea.
None of this is particularly novel from a security perspective. What has changed is the window between a weakness existing and someone finding it, and that window is now short enough that “we have it on the roadmap” is no longer a control!
If you’re building in this space, we’d like to hear from you.
Feel free to reach out to jpark@forgepointcap.com and kshih@forgepointcap.com.
This blog is also published on Margin of Safety, Jimmy and Kathryn’s Substack, as they research the practical sides of security + AI so you don’t have to.
[1] Or colloquially speaking: “How eff’d would you be?”